The most important train signal is the forecast error, which is the difference between the observed value yτy_{\tau} and the prediction y^τ\hat{y}_{\tau}, at time yτy_{\tau}: eτ=yτ−y^ττ∈{t+1,…,t+H}e_{\tau} = y_{\tau}-\hat{y}_{\tau} \qquad \qquad \tau \in \{t+1,\dots,t+H \} The train loss summarizes the forecast errors in different evaluation metrics.

1. Scale-dependent Errors

Mean Absolute Error
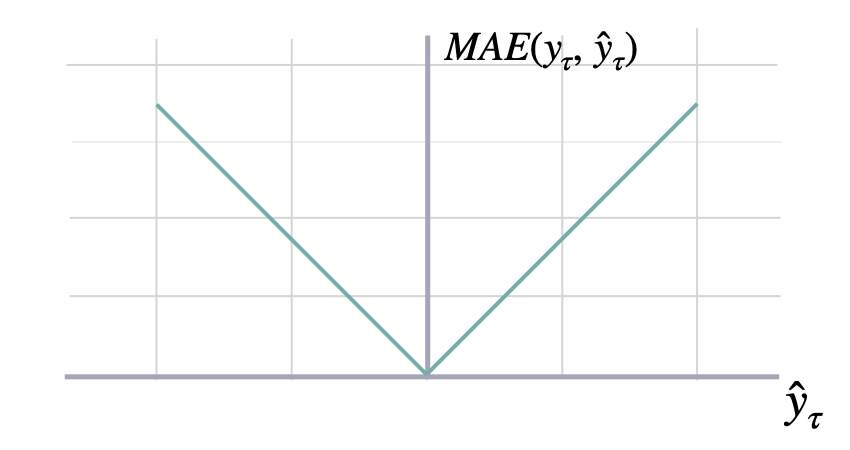
MAE(yτ,y^τ)=1H∑τ=t+1t+H∣yτ−y^τ∣\mathrm{MAE}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}_{\tau}) = \frac{1}{H} \sum^{t+H}_{\tau=t+1} |y_{\tau} - \hat{y}_{\tau}|

mae

Mean Absolute Error (MAE) MAE measures the relative prediction accuracy of a forecasting method by calculating the deviation of the prediction and the true value at a given time and averages these devations over the length of the series.

Mean Squared Error

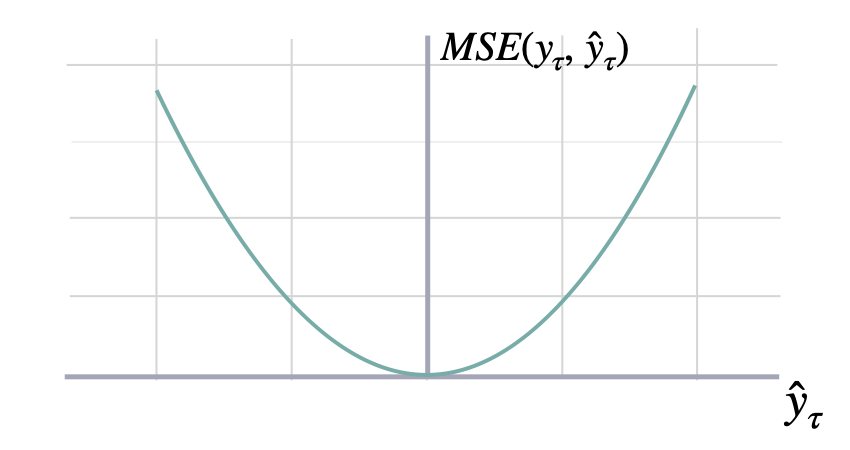
MSE(yτ,y^τ)=1H∑τ=t+1t+H(yτ−y^τ)2\mathrm{MSE}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}_{\tau}) = \frac{1}{H} \sum^{t+H}_{\tau=t+1} (y_{\tau} - \hat{y}_{\tau})^{2}

mse

Mean Squared Error (MSE) MSE measures the relative prediction accuracy of a forecasting method by calculating the squared deviation of the prediction and the true value at a given time, and averages these devations over the length of the series.

Root Mean Squared Error

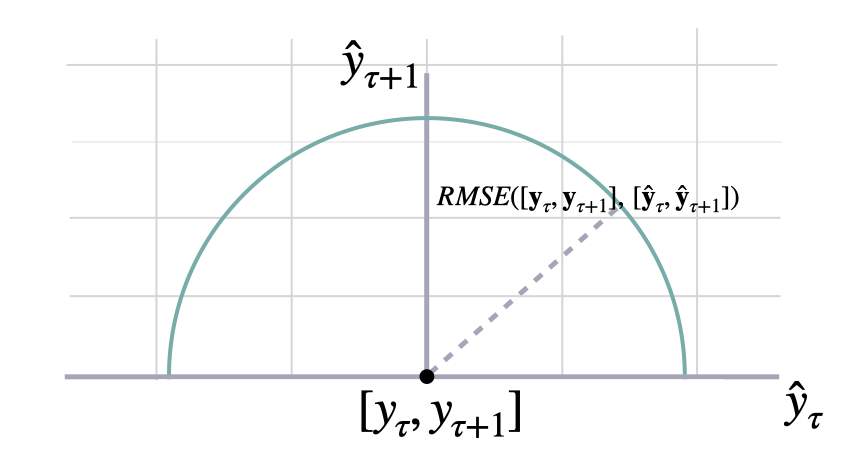
RMSE(yτ,y^τ)=1H∑τ=t+1t+H(yτ−y^τ)2\mathrm{RMSE}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}_{\tau}) = \sqrt{\frac{1}{H} \sum^{t+H}_{\tau=t+1} (y_{\tau} - \hat{y}_{\tau})^{2}}

rmse

Root Mean Squared Error (RMSE) RMSE measures the relative prediction accuracy of a forecasting method by calculating the squared deviation of the prediction and the observed value at a given time and averages these devations over the length of the series. Finally the RMSE will be in the same scale as the original time series so its comparison with other series is possible only if they share a common scale. RMSE has a direct connection to the L2 norm.

Bias

Bias(yτ,y^τ)=1H∑τ=t+1t+H(y^τ−yτ)\mathrm{Bias}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}_{\tau}) = \frac{1}{H} \sum^{t+H}_{\tau=t+1} (\hat{y}_{\tau} - \mathbf{y}_{\tau})

bias

Forecast estimator bias. Defined as prediction - actual

Cumulative Forecast Error

CFE(yτ,y^τ)=∑τ=t+1t+H(y^τ−yτ)\mathrm{CFE}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}_{\tau}) = \sum^{t+H}_{\tau=t+1} (\hat{y}_{\tau} - \mathbf{y}_{\tau})

cfe

Cumulative Forecast Error (CFE) Total signed forecast error per series. Positive values mean under forecast; negative mean over forecast.

Absolute Periods In Stock

PIS(yτ,y^τ)=∑τ=t+1t+H∣yτ−y^τ∣\mathrm{PIS}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}_{\tau}) = \sum^{t+H}_{\tau=t+1} |y_{\tau} - \hat{y}_{\tau}|

pis

Compute the raw Absolute Periods In Stock (PIS) for one or multiple models. The PIS metric sums the absolute forecast errors per series without any scaling, yielding a scale-dependent measure of bias.

Linex

Linex(yτ,y^τ)=1H∑τ=t+1t+H(ea(yτ−y^τ)−a(yτ−y^τ)−1)\mathrm{Linex}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}_{\tau}) = \frac{1}{H} \sum^{t+H}_{\tau=t+1} (e^{a(y_{\tau} - \hat{y}_{\tau})} - a(y_{\tau} - \hat{y}_{\tau}) - 1) where must be a≠0a\neq0.

linex

Linex Loss (Linear Exponential) The Linex loss penalizes over- and under-forecasting asymmetrically depending on the parameter a.
  • If a > 0, under-forecasting (y>y^y > \hat{y}) is penalized more.
  • If a < 0, over-forecasting (y^>y\hat{y} > y) is penalized more.
  • a must not be 0.
Parameters:

2. Percentage Errors

Mean Absolute Percentage Error
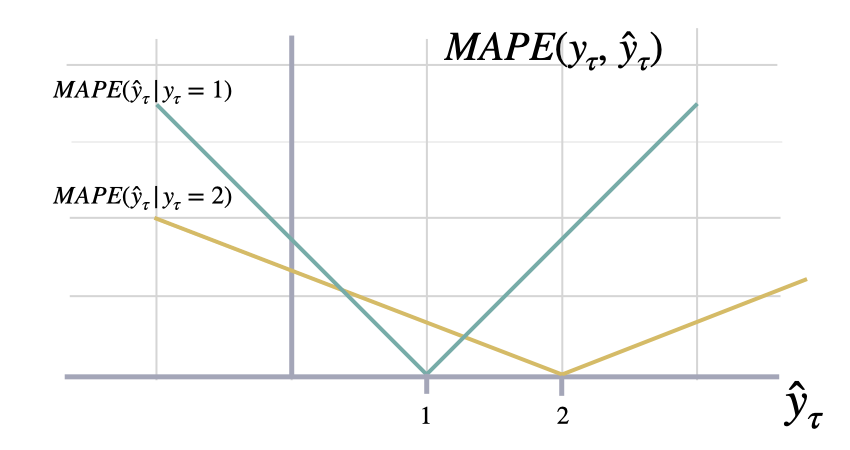
MAPE(yτ,y^τ)=1H∑τ=t+1t+H∣yτ−y^τ∣∣yτ∣\mathrm{MAPE}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}_{\tau}) = \frac{1}{H} \sum^{t+H}_{\tau=t+1} \frac{|y_{\tau}-\hat{y}_{\tau}|}{|y_{\tau}|}

mape

Mean Absolute Percentage Error (MAPE) MAPE measures the relative prediction accuracy of a forecasting method by calculating the percentual deviation of the prediction and the observed value at a given time and averages these devations over the length of the series. The closer to zero an observed value is, the higher penalty MAPE loss assigns to the corresponding error.

Symmetric Mean Absolute Percentage Error

SMAPE2(yτ,y^τ)=1H∑τ=t+1t+H∣yτ−y^τ∣∣yτ∣+∣y^τ∣\mathrm{SMAPE}_{2}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}_{\tau}) = \frac{1}{H} \sum^{t+H}_{\tau=t+1} \frac{|y_{\tau}-\hat{y}_{\tau}|}{|y_{\tau}|+|\hat{y}_{\tau}|}

smape

Symmetric Mean Absolute Percentage Error (SMAPE) SMAPE measures the relative prediction accuracy of a forecasting method by calculating the relative deviation of the prediction and the observed value scaled by the sum of the absolute values for the prediction and observed value at a given time, then averages these devations over the length of the series. This allows the SMAPE to have bounds between 0% and 100% which is desirable compared to normal MAPE that may be undetermined when the target is zero.

3. Scale-independent Errors

Mean Absolute Scaled Error
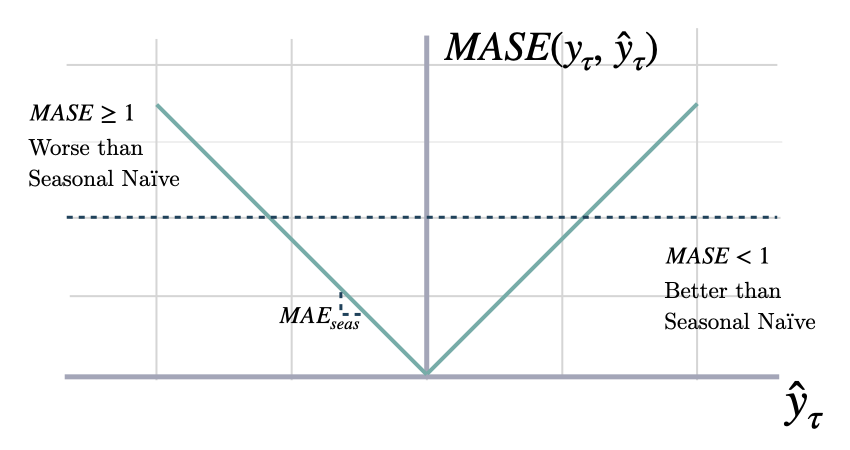
MASE(yτ,y^τ,y^τseason)=1H∑τ=t+1t+H∣yτ−y^τ∣MAE(yτ,y^τseason)\mathrm{MASE}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}_{\tau}, \mathbf{\hat{y}}^{season}_{\tau}) = \frac{1}{H} \sum^{t+H}_{\tau=t+1} \frac{|y_{\tau}-\hat{y}_{\tau}|}{\mathrm{MAE}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}^{season}_{\tau})}

mase

Mean Absolute Scaled Error (MASE) MASE measures the relative prediction accuracy of a forecasting method by comparinng the mean absolute errors of the prediction and the observed value against the mean absolute errors of the seasonal naive model. The MASE partially composed the Overall Weighted Average (OWA), used in the M4 Competition. Parameters: Returns:

Relative Mean Absolute Error

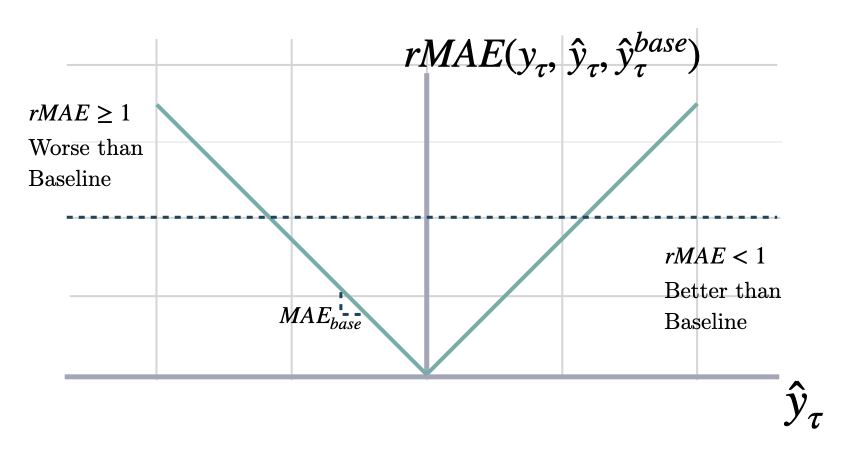
RMAE(yτ,y^τ,y^τbase)=1H∑τ=t+1t+H∣yτ−y^τ∣MAE(yτ,y^τbase)\mathrm{RMAE}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}_{\tau}, \mathbf{\hat{y}}^{base}_{\tau}) = \frac{1}{H} \sum^{t+H}_{\tau=t+1} \frac{|y_{\tau}-\hat{y}_{\tau}|}{\mathrm{MAE}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}^{base}_{\tau})}

rmae

Relative Mean Absolute Error (RMAE) Calculates the RAME between two sets of forecasts (from two different forecasting methods). A number smaller than one implies that the forecast in the numerator is better than the forecast in the denominator. Parameters: Returns:

Normalized Deviation

ND(yτ,y^τ)=∑τ=t+1t+H∣yτ−y^τ∣∑τ=t+1t+H∣yτ∣\mathrm{ND}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}_{\tau}) = \frac{\sum^{t+H}_{\tau=t+1} |y_{\tau} - \hat{y}_{\tau}|}{\sum^{t+H}_{\tau=t+1} | y_{\tau} |}

nd

Normalized Deviation (ND) ND measures the relative prediction accuracy of a forecasting method by calculating the sum of the absolute deviation of the prediction and the true value at a given time and dividing it by the sum of the absolute value of the ground truth.

Weighted Absolute Percentage Error

WAPE(yτ,y^τ)=∑τ=t+1t+H∣yτ−y^τ∣∑τ=t+1t+H∣yτ∣\mathrm{WAPE}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}_{\tau}) = \frac{\sum^{t+H}_{\tau=t+1} |y_{\tau} - \hat{y}_{\tau}|}{\sum^{t+H}_{\tau=t+1} | y_{\tau} |} WAPE (also known as wMAPE or the MAD/Mean ratio) is mathematically identical to the Normalized Deviation (ND) above; it is exposed under this more common name for convenience.

wape

Weighted Absolute Percentage Error (WAPE) WAPE = sum(|y - ŷ|) / sum(|y|) Unlike MAPE, which averages per-point percentage errors, WAPE normalizes the total absolute error by the total absolute value of the actuals. This makes it robust to zero actuals and gives more weight to higher-volume points. WAPE is mathematically identical to the Normalized Deviation (nd); it is also known as wMAPE or the MAD/Mean ratio. It is exposed under the WAPE name — the most common name for this metric in business forecasting — and delegates to nd.

Mean Squared Scaled Error

MSSE(yτ,y^τ,y^τseason)=1H∑τ=t+1t+H(yτ−y^τ)2MSE(yτ,y^τseason)\mathrm{MSSE}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}_{\tau}, \mathbf{\hat{y}}^{season}_{\tau}) = \frac{1}{H} \sum^{t+H}_{\tau=t+1} \frac{(y_{\tau}-\hat{y}_{\tau})^2}{\mathrm{MSE}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}^{season}_{\tau})}

msse

Mean Squared Scaled Error (MSSE) MSSE measures the relative prediction accuracy of a forecasting method by comparinng the mean squared errors of the prediction and the observed value against the mean squared errors of the seasonal naive model. Parameters: Returns:

Root Mean Squared Scaled Error

RMSSE(yτ,y^τ,y^τseason)=1H∑τ=t+1t+H(yτ−y^τ)2MSE(yτ,y^τseason)\mathrm{RMSSE}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}_{\tau}, \mathbf{\hat{y}}^{season}_{\tau}) = \sqrt{\frac{1}{H} \sum^{t+H}_{\tau=t+1} \frac{(y_{\tau}-\hat{y}_{\tau})^2}{\mathrm{MSE}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}^{season}_{\tau})}}

rmsse

Root Mean Squared Scaled Error (RMSSE) MSSE measures the relative prediction accuracy of a forecasting method by comparinng the mean squared errors of the prediction and the observed value against the mean squared errors of the seasonal naive model. Parameters: Returns:

Scaled Absolute Periods In Stock

PIS(yτ,y^τ)=∑τ=t+1t+H∣yτ−y^τ∣yˉ\mathrm{PIS}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}_{\tau}) = \sum^{t+H}_{\tau=t+1} \frac{|y_{\tau} - \hat{y}_{\tau}|}{\bar{y}} where yˉ=1H∑τ=t+1t+Hyτ\bar{y}=\frac{1}{H}\sum^{t+H}_{\tau=t+1} y_{\tau}.

spis

Compute the scaled Absolute Periods In Stock (sAPIS) for one or multiple models. The sPIS metric scales the sum of absolute forecast errors by the mean in-sample demand, yielding a scale-independent bias measure that can be aggregated across series. Parameters: Returns:

4. Probabilistic Errors

Quantile Loss
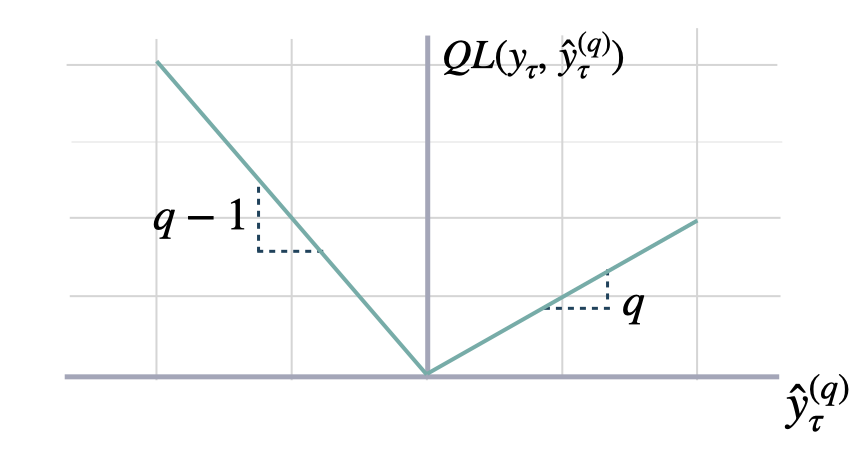
QL(yτ,y^τ(q))=1H∑τ=t+1t+H((1−q) (y^τ(q)−yτ)++q (yτ−y^τ(q))+)\mathrm{QL}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}^{(q)}_{\tau}) = \frac{1}{H} \sum^{t+H}_{\tau=t+1} \Big( (1-q)\,( \hat{y}^{(q)}_{\tau} - y_{\tau} )_{+} + q\,( y_{\tau} - \hat{y}^{(q)}_{\tau} )_{+} \Big)

quantile_loss

Quantile Loss (QL) QL measures the deviation of a quantile forecast. By weighting the absolute deviation in a non symmetric way, the loss pays more attention to under or over estimation. A common value for q is 0.5 for the deviation from the median. Parameters: Returns:

Scaled Quantile Loss

SQL(yτ,y^τ(q))=1H∑τ=t+1t+H(1−q) (y^τ(q)−yτ)++q (yτ−y^τ(q))+MAE(yτ,y^τseason)\mathrm{SQL}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}^{(q)}_{\tau}) = \frac{1}{H} \sum^{t+H}_{\tau=t+1} \frac{(1-q)\,( \hat{y}^{(q)}_{\tau} - y_{\tau} )_{+} + q\,( y_{\tau} - \hat{y}^{(q)}_{\tau} )_{+}}{\mathrm{MAE}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}^{season}_{\tau})}

scaled_quantile_loss

Scaled Quantile Loss (SQL) SQL measures the deviation of a quantile forecast scaled by the mean absolute errors of the seasonal naive model. By weighting the absolute deviation in a non symmetric way, the loss pays more attention to under or over estimation. A common value for q is 0.5 for the deviation from the median. This was the official measure used in the M5 Uncertainty competition with seasonality = 1. Parameters: Returns:

Multi-Quantile Loss

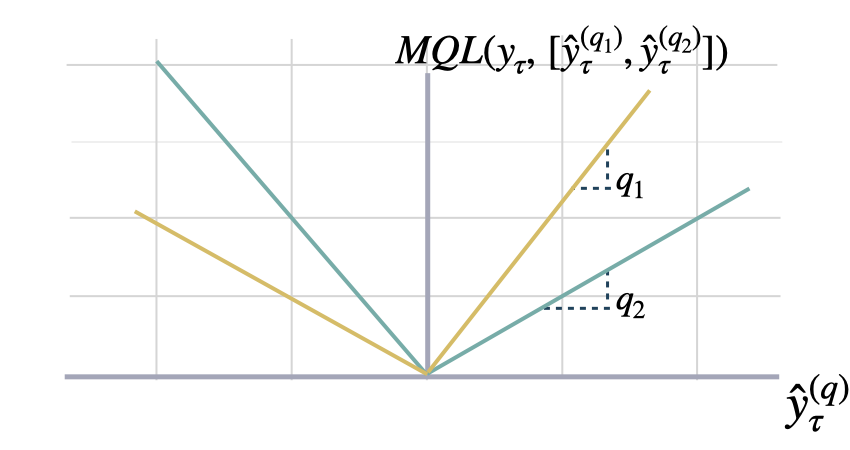
MQL(yτ,[y^τ(q1),...,y^τ(qn)])=1n∑qiQL(yτ,y^τ(qi))\mathrm{MQL}(\mathbf{y}_{\tau}, [\mathbf{\hat{y}}^{(q_{1})}_{\tau}, ... ,\hat{y}^{(q_{n})}_{\tau}]) = \frac{1}{n} \sum_{q_{i}} \mathrm{QL}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}^{(q_{i})}_{\tau})

mqloss

Multi-Quantile loss (MQL) MQL calculates the average multi-quantile Loss for a given set of quantiles, based on the absolute difference between predicted quantiles and observed values. The limit behavior of MQL allows to measure the accuracy of a full predictive distribution with the continuous ranked probability score (CRPS). This can be achieved through a numerical integration technique, that discretizes the quantiles and treats the CRPS integral with a left Riemann approximation, averaging over uniformly distanced quantiles. Parameters: Returns:

Scaled Multi-Quantile Loss

MQL(yτ,[y^τ(q1),...,y^τ(qn)])=1n∑qiQL(yτ,y^τ(qi))MAE(yτ,y^τseason)\mathrm{MQL}(\mathbf{y}_{\tau}, [\mathbf{\hat{y}}^{(q_{1})}_{\tau}, ... ,\hat{y}^{(q_{n})}_{\tau}]) = \frac{1}{n} \sum_{q_{i}} \frac{\mathrm{QL}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}^{(q_{i})}_{\tau})}{\mathrm{MAE}(\mathbf{y}_{\tau}, \mathbf{\hat{y}}^{season}_{\tau})}

scaled_mqloss

Scaled Multi-Quantile loss (SMQL) SMQL calculates the average multi-quantile Loss for a given set of quantiles, based on the absolute difference between predicted quantiles and observed values scaled by the mean absolute errors of the seasonal naive model. The limit behavior of MQL allows to measure the accuracy of a full predictive distribution with the continuous ranked probability score (CRPS). This can be achieved through a numerical integration technique, that discretizes the quantiles and treats the CRPS integral with a left Riemann approximation, averaging over uniformly distanced quantiles. This was the official measure used in the M5 Uncertainty competition with seasonality = 1. Parameters: Returns:

Coverage

coverage

Coverage of y with y_hat_lo and y_hat_hi. Parameters: Returns:

Winkler Score

Winklerα(yτ,ℓα,τ,uα,τ)=1H∑τ=t+1t+HWα,τ\mathrm{Winkler}_{\alpha}(\mathbf{y}_{\tau}, \boldsymbol{\ell}_{\alpha,\tau}, \mathbf{u}_{\alpha,\tau}) = \frac{1}{H} \sum^{t+H}_{\tau=t+1} W_{\alpha,\tau} where Wα,τ={(uα,τ−ℓα,τ)+2α(ℓα,τ−yτ)if yτ<ℓα,τ(uα,τ−ℓα,τ)if ℓα,τ≤yτ≤uα,τ(uα,τ−ℓα,τ)+2α(yτ−uα,τ)if yτ>uα,τW_{\alpha,\tau} = \begin{cases} (u_{\alpha,\tau} - \ell_{\alpha,\tau}) + \frac{2}{\alpha} (\ell_{\alpha,\tau} - y_{\tau}) & \text{if } y_{\tau} < \ell_{\alpha,\tau} \\ (u_{\alpha,\tau} - \ell_{\alpha,\tau}) & \text{if } \ell_{\alpha,\tau} \le y_{\tau} \le u_{\alpha,\tau} \\ (u_{\alpha,\tau} - \ell_{\alpha,\tau}) + \frac{2}{\alpha} (y_{\tau} - u_{\alpha,\tau}) & \text{if } y_{\tau} > u_{\alpha,\tau} \end{cases} where [ℓα,τ,uα,τ][\ell_{\alpha,\tau}, u_{\alpha,\tau}] is the 100(1−α)%100(1-\alpha)\% prediction interval and α=1−level/100\alpha = 1 - \text{level}/100.

winkler_score

Winkler Score The Winkler score evaluates a prediction interval by rewarding narrow intervals and penalizing observations that fall outside them. For a 100(1-alpha)% prediction interval [lo, hi] and an observation y, with alpha = 1 - level/100, it is defined as:
  • The interval width (hi - lo), if the observation lies within the interval (between lo and hi, inclusive).
  • (hi - lo) + (2/alpha)(lo - y), if the observation lies below the interval.
  • (hi - lo) + (2/alpha)(y - hi), if the observation lies above the interval.
Lower scores are better. Intervals that are both narrow and well calibrated are rewarded, while observations outside the interval incur on a penalty. Parameters: Returns:

Calibration

calibration

Fraction of y that is lower than the model’s predictions. Parameters: Returns:

CRPS

sCRPS(F^τ,yτ)=2N∑i∫01QL(F^i,τ,yi,τ)q∑i∣yi,τ∣dq\mathrm{sCRPS}(\hat{F}_{\tau}, \mathbf{y}_{\tau}) = \frac{2}{N} \sum_{i} \int^{1}_{0} \frac{\mathrm{QL}(\hat{F}_{i,\tau}, y_{i,\tau})_{q}}{\sum_{i} | y_{i,\tau} |} dq Where F^τ\hat{F}_{\tau} is the an estimated multivariate distribution, and yi,τy_{i,\tau} are its realizations.

scaled_crps

Scaled Continues Ranked Probability Score Calculates a scaled variation of the CRPS, as proposed by Rangapuram (2021), to measure the accuracy of predicted quantiles y_hat compared to the observation y. This metric averages percentual weighted absolute deviations as defined by the quantile losses. Parameters: Returns:

Tweedie Deviance

For a set of forecasts {μi}i=1N\{\mu_i\}_{i=1}^N and observations {yi}i=1N\{y_i\}_{i=1}^N, the mean Tweedie deviance with power pp is TDp(μ,y)=1N∑i=1Ndp(yi,μi)\mathrm{TD}_{p}(\boldsymbol{\mu}, \mathbf{y}) = \frac{1}{N} \sum_{i=1}^{N} d_{p}(y_i, \mu_i) where the unit-scaled deviance for each pair (y,μ)(y,\mu) is dp(y,μ)=2{y2−p(1−p)(2−p)  −  y μ1−p1−p  +  μ2−p2−p,p∉{1,2},y ln⁡ ⁣yμ  −  (y−μ),p=1(Poisson deviance),yμ  −  ln⁡ ⁣yμ  −  1,p=2(Gamma deviance).d_{p}(y,\mu) = 2 \begin{cases} \displaystyle \frac{y^{2-p}}{(1-p)(2-p)} \;-\; \frac{y\,\mu^{1-p}}{1-p} \;+\; \frac{\mu^{2-p}}{2-p}, & p \notin\{1,2\},\\[1em] \displaystyle y\,\ln\!\frac{y}{\mu}\;-\;(y-\mu), & p = 1\quad(\text{Poisson deviance}),\\[0.5em] \displaystyle \frac{y}{\mu}\;-\;\ln\!\frac{y}{\mu}\;-\;1, & p = 2\quad(\text{Gamma deviance}). \end{cases}
  • yiy_i are the true values, μi\mu_i the predicted means.
  • pp controls the variance relationship Var(Y)∝μp\mathrm{Var}(Y)\propto\mu^{p}.
  • When 1<p<21<p<2, this smoothly interpolates between Poisson (p=1p=1) and Gamma (p=2p=2) deviance.

tweedie_deviance

Compute the Tweedie deviance loss for one or multiple models, grouped by an identifier. Each group’s deviance is calculated using the mean_tweedie_deviance function, which measures the deviation between actual and predicted values under the Tweedie distribution. The power parameter defines the specific compound distribution:
  • 1: Poisson
  • (1, 2): Compound Poisson-Gamma
  • 2: Gamma
  • 2: Inverse Gaussian
Parameters: Returns: