> ## Documentation Index
> Fetch the complete documentation index at: https://nixtlaverse.nixtla.io/llms.txt
> Use this file to discover all available pages before exploring further.
> SOFTSSharp: SOFTS extension with stochastic variable-position encoding for multivariate time series forecasting.
# SOFTSSharp
SOFTSSharp extends SOFTS by stochastically adding variable-position embeddings and multiple dropout layers inside the STAD aggregation-redistribution component, aiming to improve forecasting accuracy while preserving linear complexity.
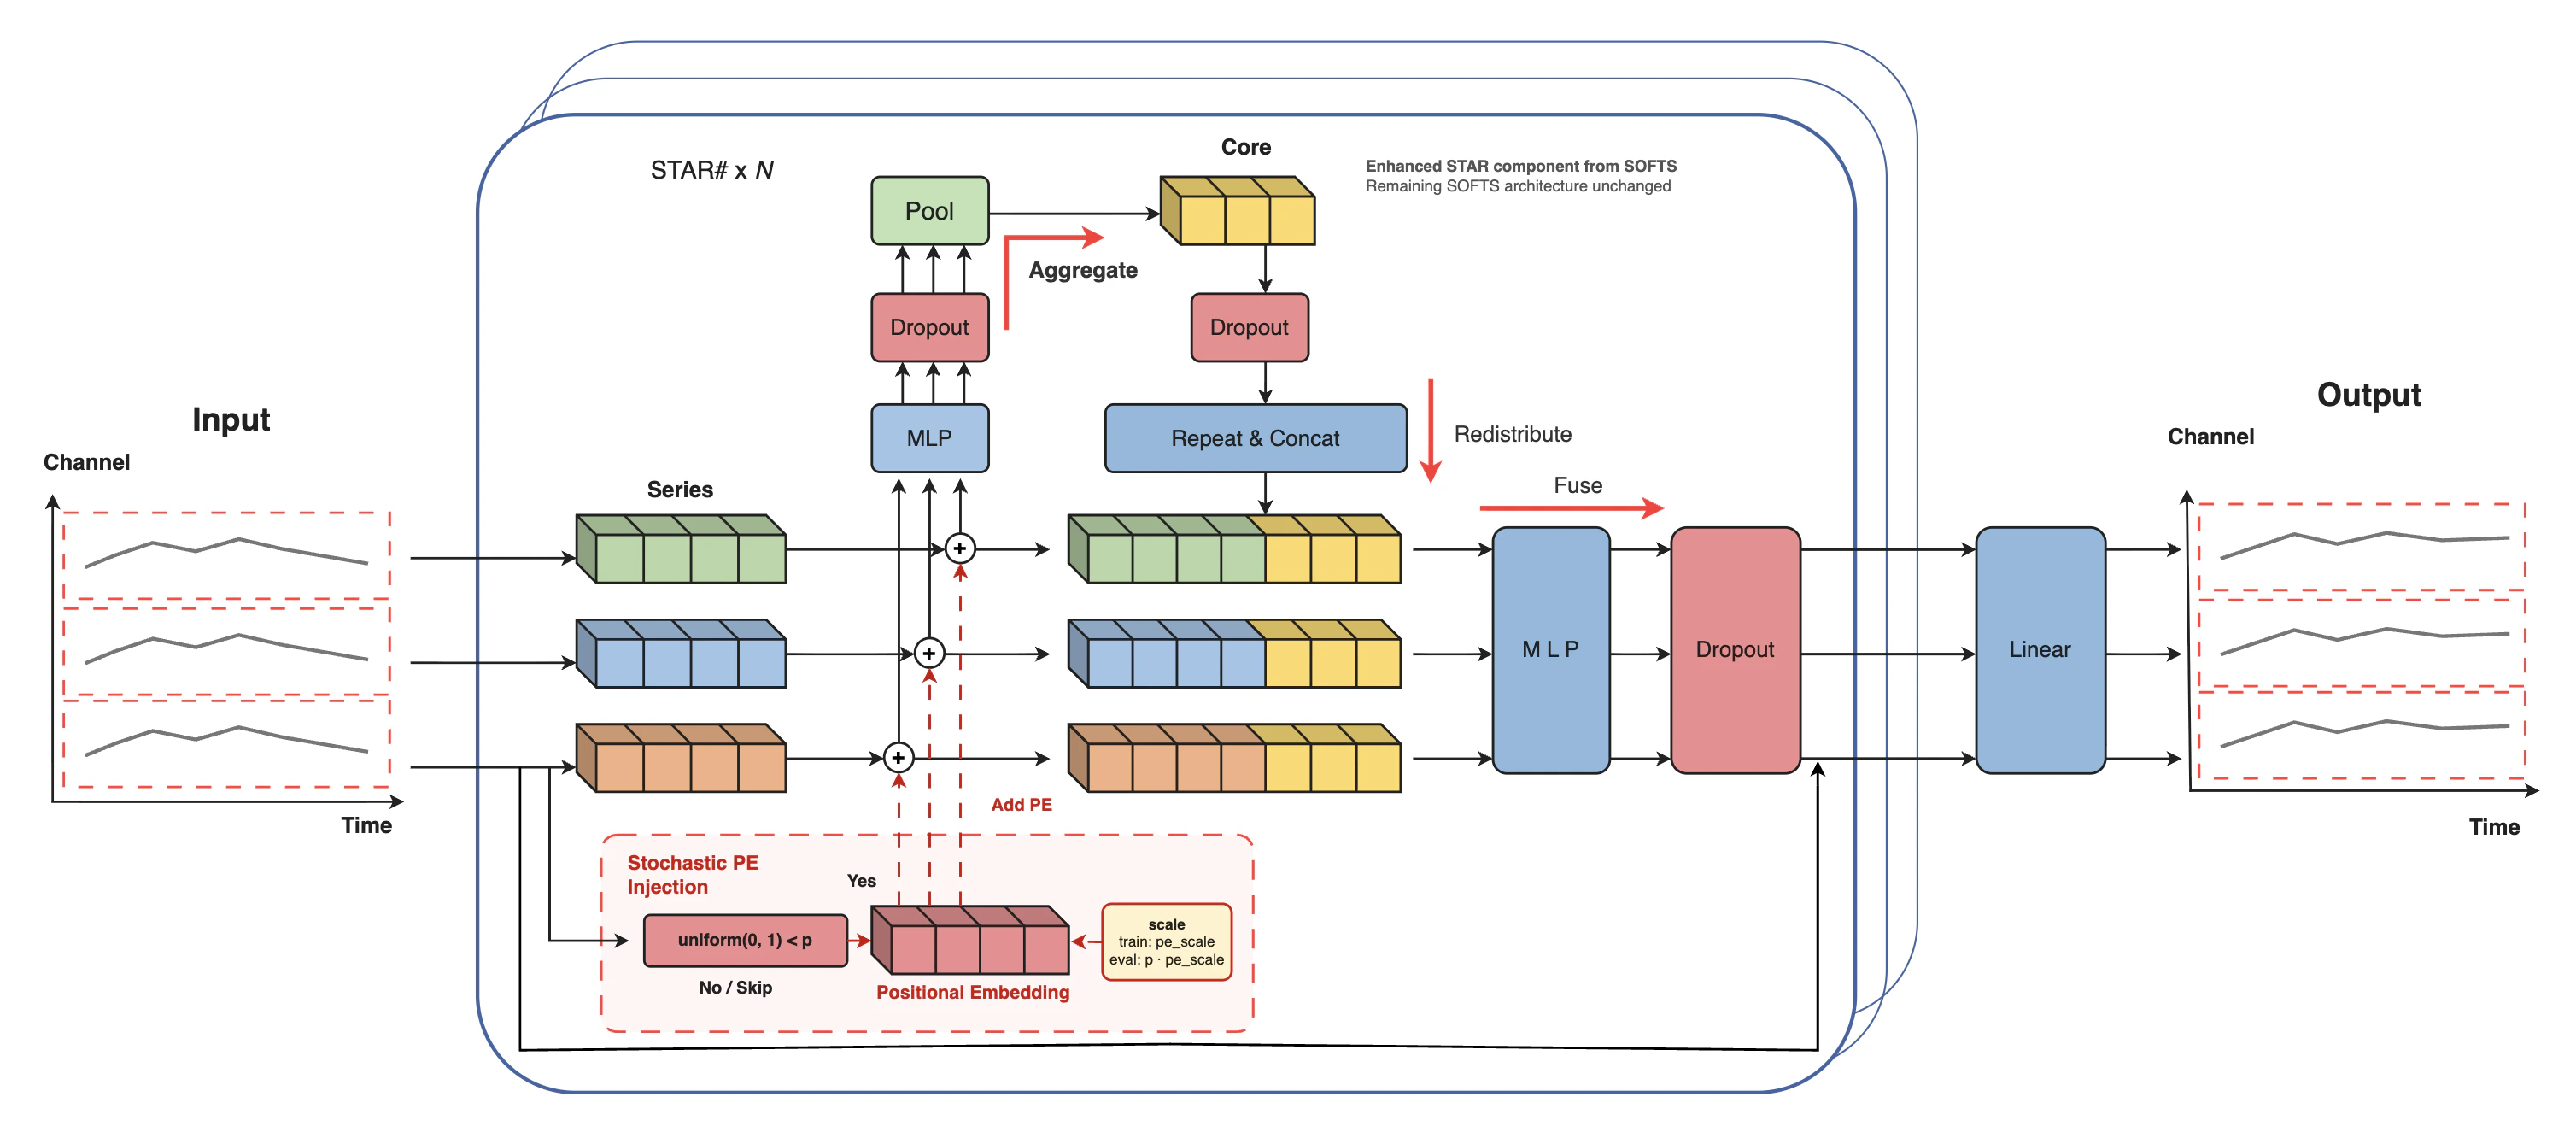 *Figure 1. Architecture of SOFTSSharp*
## 1. SOFTSSharp
### `SOFTSSharp`
```python theme={null}
SOFTSSharp(
h,
input_size,
n_series,
futr_exog_list=None,
hist_exog_list=None,
stat_exog_list=None,
exclude_insample_y=False,
hidden_size=512,
d_core=512,
e_layers=2,
d_ff=2048,
dropout=0.1,
pe_keep_prob=0.5,
use_norm=True,
loss=MAE(),
valid_loss=None,
max_steps=1000,
learning_rate=0.001,
num_lr_decays=-1,
early_stop_patience_steps=-1,
val_monitor="ptl/val_loss",
val_check_steps=100,
batch_size=32,
valid_batch_size=None,
windows_batch_size=32,
inference_windows_batch_size=32,
start_padding_enabled=False,
training_data_availability_threshold=0.0,
step_size=1,
scaler_type="identity",
random_seed=1,
drop_last_loader=False,
alias=None,
optimizer=None,
optimizer_kwargs=None,
lr_scheduler=None,
lr_scheduler_kwargs=None,
dataloader_kwargs=None,
**trainer_kwargs
)
```
Bases:
[BaseModel](#neuralforecast.common._base_model.BaseModel)
SOFTSSharp
SOFTS# (SOFTSSharp) extends SOFTS by stochastically adding
variable-position embeddings and multiple dropout layers inside the STAD
component.
**Parameters:**
| Name | Type | Description | Default |
| - | - | - | - |
| `h` | [int](#int) | Forecast horizon. | *required* |
| `input_size` | [int](#int) | Autoregressive inputs size. | *required* |
| `n_series` | [int](#int) | Number of time-series. | *required* |
| `hidden_size` | [int](#int) | Dimension of the model. | 512 |
| `d_core` | [int](#int) | Dimension of core in STADSharp. | 512 |
| `e_layers` | [int](#int) | Number of encoder layers. | 2 |
| `d_ff` | [int](#int) | Dimension of fully-connected layer. | 2048 |
| `dropout` | [float](#float) | Dropout rate. | 0.1 |
| `pe_keep_prob` | [float](#float) | probability of applying variable-position encoding during training. During inference, the positional encoding is scaled by this value. | 0.5 |
| `use_norm` | [bool](#bool) | Whether to normalize or not. | True |
| `loss` | PyTorch module | Instantiated train loss class from [losses collection](./losses.pytorch.html). | [MAE](#neuralforecast.losses.pytorch.MAE)() |
| `valid_loss` | PyTorch module | Instantiated valid loss class from [losses collection](./losses.pytorch.html). | None |
| `max_steps` | [int](#int) | Maximum number of training steps. | 1000 |
| `learning_rate` | [float](#float) | Learning rate between (0, 1). | 0.001 |
| `num_lr_decays` | [int](#int) | Number of learning rate decays, evenly distributed across max\_steps. | -1 |
| `early_stop_patience_steps` | [int](#int) | Number of validation iterations before early stopping. | -1 |
| `val_monitor` | [str](#str) | Metric to monitor for early stopping. | 'ptl/val\_loss' |
| `val_check_steps` | [int](#int) | Number of training steps between every validation loss check. | 100 |
| `batch_size` | [int](#int) | Number of different series in each batch. | 32 |
| `valid_batch_size` | [int](#int) | Number of different series in each validation and test batch, if None uses batch\_size. | None |
| `windows_batch_size` | [int](#int) | Number of windows to sample in each training batch, default uses all. | 32 |
| `inference_windows_batch_size` | [int](#int) | Number of windows to sample in each inference batch, -1 uses all. | 32 |
| `start_padding_enabled` | [bool](#bool) | If True, the model will pad the time series with zeros at the beginning, by input size. | False |
| `step_size` | [int](#int) | Step size between each window of temporal data. | 1 |
| `scaler_type` | [str](#str) | Type of scaler for temporal inputs normalization. | 'identity' |
| `random_seed` | [int](#int) | Random seed for pytorch initializer and numpy generators. | 1 |
| `drop_last_loader` | [bool](#bool) | If True `TimeSeriesDataLoader` drops last non-full batch. | False |
| `alias` | [str](#str) | Optional custom name of the model. | None |
References
* [Hrvoje Ljubić. "SOFTSSharp: SOFTS extension with stochastic variable-position encoding", reference implementation; manuscript in preparation](https://github.com/hljubic/SOFTSsharp)
* [Hrvoje Ljubić, Goran Martinović, Tomislav Volarić, Robert Rozić. "SOFTS++: Fast and accurate linear model for multivariate long-term time series forecasting", related work](https://doi.org/10.1177/1088467X251380055)
* [Lu Han, Xu-Yang Chen, Han-Jia Ye, De-Chuan Zhan. "SOFTS: Efficient Multivariate Time Series Forecasting with Series-Core Fusion"](https://arxiv.org/pdf/2404.14197)
#### `SOFTSSharp.fit`
```python theme={null}
fit(
dataset, val_size=0, test_size=0, random_seed=None, distributed_config=None
)
```
Fit.
The `fit` method, optimizes the neural network's weights using the
initialization parameters (`learning_rate`, `windows_batch_size`, ...)
and the `loss` function as defined during the initialization.
Within `fit` we use a PyTorch Lightning `Trainer` that
inherits the initialization's `self.trainer_kwargs`, to customize
its inputs, see [PL's trainer arguments](https://pytorch-lightning.readthedocs.io/en/stable/api/pytorch_lightning.trainer.trainer.Trainer.html?highlight=trainer).
The method is designed to be compatible with SKLearn-like classes
and in particular to be compatible with the StatsForecast library.
By default the `model` is not saving training checkpoints to protect
disk memory, to get them change `enable_checkpointing=True` in `__init__`.
**Parameters:**
| Name | Type | Description | Default |
| - | - | - | - |
| `dataset` | [TimeSeriesDataset](#TimeSeriesDataset) | NeuralForecast's `TimeSeriesDataset`, see [documentation](./tsdataset.html). | *required* |
| `val_size` | [int](#int) | Validation size for temporal cross-validation. | 0 |
| `random_seed` | [int](#int) | Random seed for pytorch initializer and numpy generators, overwrites model.**init**'s. | None |
| `test_size` | [int](#int) | Test size for temporal cross-validation. | 0 |
**Returns:**
| Type | Description |
| - | - |
| None | |
#### `SOFTSSharp.predict`
```python theme={null}
predict(
dataset,
test_size=None,
step_size=1,
random_seed=None,
quantiles=None,
h=None,
explainer_config=None,
**data_module_kwargs
)
```
Predict.
Neural network prediction with PL's `Trainer` execution of `predict_step`.
**Parameters:**
| Name | Type | Description | Default |
| - | - | - | - |
| `dataset` | [TimeSeriesDataset](#TimeSeriesDataset) | NeuralForecast's `TimeSeriesDataset`, see [documentation](./tsdataset.html). | *required* |
| `test_size` | [int](#int) | Test size for temporal cross-validation. | None |
| `step_size` | [int](#int) | Step size between each window. | 1 |
| `random_seed` | [int](#int) | Random seed for pytorch initializer and numpy generators, overwrites model.**init**'s. | None |
| `quantiles` | [list](#list) | Target quantiles to predict. | None |
| `h` | [int](#int) | Prediction horizon, if None, uses the model's fitted horizon. Defaults to None. | None |
| `explainer_config` | [dict](#dict) | configuration for explanations. | None |
| `**data_module_kwargs` | [dict](#dict) | PL's TimeSeriesDataModule args, see [documentation](https://pytorch-lightning.readthedocs.io/en/1.6.1/extensions/datamodules.html#using-a-datamodule). | {} |
**Returns:**
| Type | Description |
| - | - |
| None | |
### Usage example
```python theme={null}
import pandas as pd
import matplotlib.pyplot as plt
from neuralforecast import NeuralForecast
from neuralforecast.models import SOFTSSharp
from neuralforecast.utils import AirPassengersPanel, AirPassengersStatic
from neuralforecast.losses.pytorch import MASE
Y_train_df = AirPassengersPanel[AirPassengersPanel.ds=AirPassengersPanel['ds'].values[-12]].reset_index(drop=True)
model = SOFTSSharp(h=12,
input_size=24,
n_series=2,
hidden_size=256,
d_core=256,
e_layers=2,
d_ff=64,
dropout=0.1,
pe_keep_prob=0.5,
use_norm=True,
loss=MASE(seasonality=4),
early_stop_patience_steps=3,
batch_size=32)
fcst = NeuralForecast(models=[model], freq='ME')
fcst.fit(df=Y_train_df, static_df=AirPassengersStatic, val_size=12)
forecasts = fcst.predict(futr_df=Y_test_df)
fig, ax = plt.subplots(1, 1, figsize = (20, 7))
Y_hat_df = forecasts.reset_index(drop=False).drop(columns=['unique_id','ds'])
plot_df = pd.concat([Y_test_df, Y_hat_df], axis=1)
plot_df = pd.concat([Y_train_df, plot_df])
plot_df = plot_df[plot_df.unique_id=='Airline1'].drop('unique_id', axis=1)
plt.plot(plot_df['ds'], plot_df['y'], c='black', label='True')
plt.plot(plot_df['ds'], plot_df['SOFTSSharp'], c='blue', label='Forecast')
ax.set_title('AirPassengers Forecast', fontsize=22)
ax.set_ylabel('Monthly Passengers', fontsize=20)
ax.set_xlabel('Year', fontsize=20)
ax.legend(prop={'size': 15})
ax.grid()
```
## 2. Auxiliary functions
### `PositionalEmbedding`
```python theme={null}
PositionalEmbedding(d_series, max_len=5000)
```
Bases: [Module](#torch.nn.Module)
### `STADSharp`
```python theme={null}
STADSharp(d_series, d_core, dropout_rate=0.1, pe_keep_prob=0.5)
```
Bases: [Module](#torch.nn.Module)
STar Aggregate Dispatch Module with stochastic variable-position encoding.
## Related topics
- [Forecasting Models](/neuralforecast/docs/capabilities/overview.html.md)
- [Energy load](/synforecast/docs/generators/domain/energy_load.html.md)
- [Automatic Forecasting](/neuralforecast/models.html.md)