> ## Documentation Index
> Fetch the complete documentation index at: https://nixtlaverse.nixtla.io/llms.txt
> Use this file to discover all available pages before exploring further.
> MLP: Multi-Layer Perceptron for time series forecasting. Simple feedforward neural network with ReLU activations and autoregressive structure for predictions.
# MLP
One of the simplest neural architectures are Multi Layer Perceptrons (`MLP`)
composed of stacked Fully Connected Neural Networks trained with
backpropagation. Each node in the architecture is capable of modeling
non-linear relationships granted by their activation functions. Novel
activations like Rectified Linear Units (`ReLU`) have greatly improved the
ability to fit deeper networks overcoming gradient vanishing problems that
were associated with `Sigmoid` and `TanH` activations. For the forecasting
task the last layer is changed to follow a auto-regression
problem.
**References**
-[Rosenblatt, F. (1958). "The perceptron: A probabilistic model for information storage and organization in the brain."](https://psycnet.apa.org/record/1959-09865-001)
-[Fukushima, K. (1975). "Cognitron: A self-organizing multilayered neural network."](https://pascal-francis.inist.fr/vibad/index.php?action=getRecordDetail\&idt=PASCAL7750396723)
-[Vinod Nair, Geoffrey E. Hinton (2010). "Rectified Linear Units Improve Restricted Boltzmann Machines"](https://www.cs.toronto.edu/~fritz/absps/reluICML.pdf)
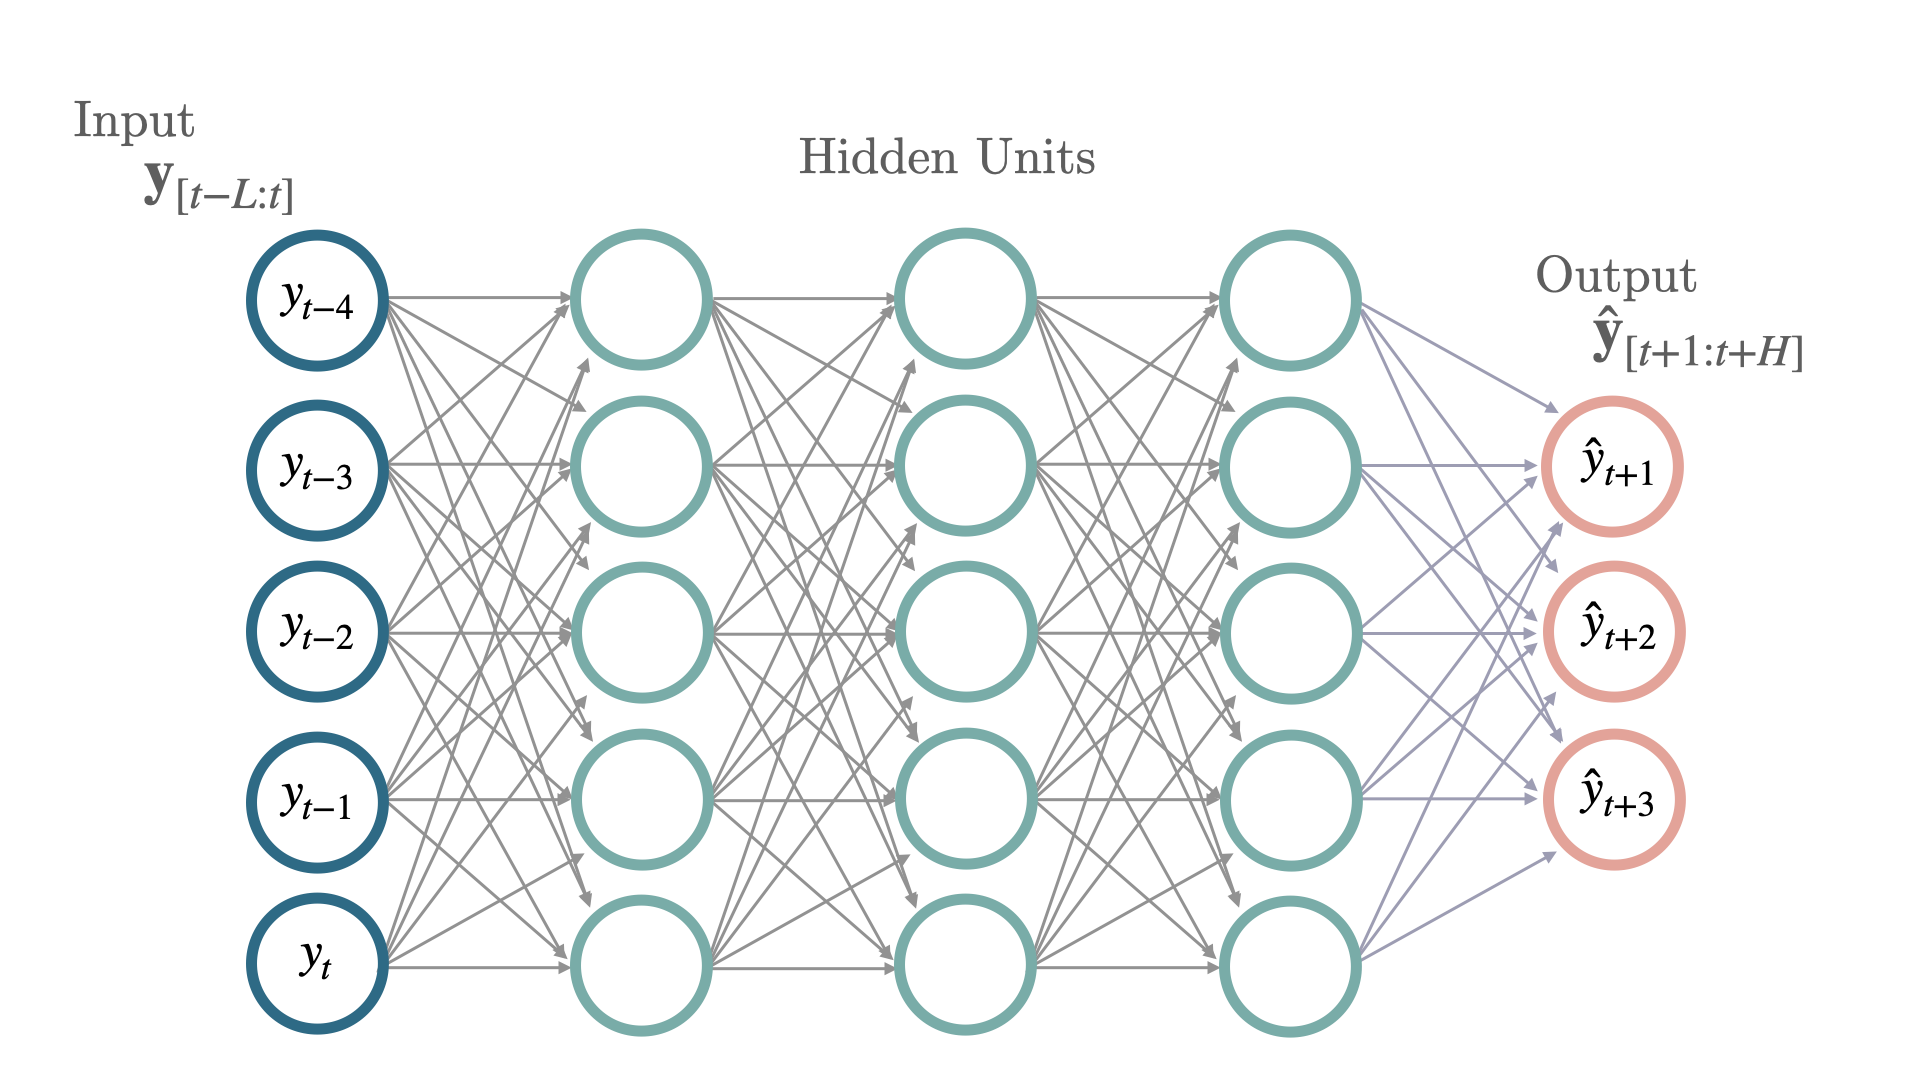 *Figure 1. Three layer MLP with
autorregresive inputs.*
## MLP
### `MLP`
```python theme={null}
MLP(
h,
input_size,
stat_exog_list=None,
hist_exog_list=None,
futr_exog_list=None,
cat_exog_list=None,
categorical_cardinalities=None,
cat_emb_dim="fastai",
exclude_insample_y=False,
num_layers=2,
hidden_size=1024,
loss=MAE(),
valid_loss=None,
max_steps=1000,
learning_rate=0.001,
num_lr_decays=-1,
early_stop_patience_steps=-1,
val_monitor="ptl/val_loss",
val_check_steps=100,
batch_size=32,
valid_batch_size=None,
windows_batch_size=1024,
inference_windows_batch_size=-1,
start_padding_enabled=False,
training_data_availability_threshold=0.0,
step_size=1,
scaler_type="identity",
random_seed=1,
drop_last_loader=False,
alias=None,
optimizer=None,
optimizer_kwargs=None,
lr_scheduler=None,
lr_scheduler_kwargs=None,
dataloader_kwargs=None,
**trainer_kwargs
)
```
Bases:
[BaseModel](#neuralforecast.common._base_model.BaseModel)
MLP
Simple Multi Layer Perceptron architecture (MLP).
This deep neural network has constant units through its layers, each with
ReLU non-linearities, it is trained using ADAM stochastic gradient descent.
The network accepts static, historic and future exogenous data, flattens
the inputs and learns fully connected relationships against the target variable.
**Parameters:**
| Name | Type | Description | Default |
| - | - | - | - |
| `h` | [int](#int) | forecast horizon. | *required* |
| `input_size` | [int](#int) | considered autorregresive inputs (lags), y=\[1,2,3,4] input\_size=2 -> lags=\[1,2]. | *required* |
| `stat_exog_list` | str list | static exogenous columns. | None |
| `hist_exog_list` | str list | historic exogenous columns. | None |
| `futr_exog_list` | str list | future exogenous columns. | None |
| `cat_exog_list` | str list | exogenous columns (from `hist_exog_list` / `futr_exog_list` / `stat_exog_list`) to embed instead of scale. | None |
| `categorical_cardinalities` | [dict](#dict) | mapping from each categorical column to its number of distinct categories. | None |
| `cat_emb_dim` | [str](#str) or [int](#int) | categorical embedding size strategy ('fastai', 'sqrt', 'half') or an explicit integer. | 'fastai' |
| `exclude_insample_y` | [bool](#bool) | the model skips the autoregressive features y\[t-input\_size:t] if True. | False |
| `num_layers` | [int](#int) | number of layers for the MLP. | 2 |
| `hidden_size` | [int](#int) | number of units for each layer of the MLP. | 1024 |
| `loss` | PyTorch module | instantiated train loss class from [losses collection](./losses.pytorch.html). | [MAE](#neuralforecast.losses.pytorch.MAE)() |
| `valid_loss` | PyTorch module | instantiated valid loss class from [losses collection](./losses.pytorch.html). | None |
| `max_steps` | [int](#int) | maximum number of training steps. | 1000 |
| `learning_rate` | [float](#float) | Learning rate between (0, 1). | 0.001 |
| `num_lr_decays` | [int](#int) | Number of learning rate decays, evenly distributed across max\_steps. | -1 |
| `early_stop_patience_steps` | [int](#int) | Number of validation iterations before early stopping. | -1 |
| `val_monitor` | [str](#str) | metric to monitor for early stopping. Valid options: "ptl/val\_loss", "valid\_loss", "train\_loss". Default: "ptl/val\_loss". | 'ptl/val\_loss' |
| `val_check_steps` | [int](#int) | Number of training steps between every validation loss check. | 100 |
| `batch_size` | [int](#int) | number of different series in each batch. | 32 |
| `valid_batch_size` | [int](#int) | number of different series in each validation and test batch, if None uses batch\_size. | None |
| `windows_batch_size` | [int](#int) | number of windows to sample in each training batch, default uses all. | 1024 |
| `inference_windows_batch_size` | [int](#int) | number of windows to sample in each inference batch, -1 uses all. | -1 |
| `start_padding_enabled` | [bool](#bool) | if True, the model will pad the time series with zeros at the beginning, by input size. | False |
| `training_data_availability_threshold` | [Union](#Union)\[[float](#float), [List](#List)\[[float](#float)]] | minimum fraction of valid data points required for training windows. Single float applies to both insample and outsample; list of two floats specifies \[insample\_fraction, outsample\_fraction]. Default 0.0 allows windows with only 1 valid data point (current behavior). | 0.0 |
| `step_size` | [int](#int) | step size between each window of temporal data. | 1 |
| `scaler_type` | [str](#str) | type of scaler for temporal inputs normalization see [temporal scalers](https://github.com/Nixtla/neuralforecast/blob/main/neuralforecast/common/_scalers.py). | 'identity' |
| `random_seed` | [int](#int) | random\_seed for pytorch initializer and numpy generators. | 1 |
| `drop_last_loader` | [bool](#bool) | if True `TimeSeriesDataLoader` drops last non-full batch. | False |
| `alias` | [str](#str) | optional, Custom name of the model. | None |
| `optimizer` | Subclass of 'torch.optim.Optimizer' | optional, user specified optimizer instead of the default choice (Adam). | None |
| `optimizer_kwargs` | [dict](#dict) | optional, list of parameters used by the user specified `optimizer`. | None |
| `lr_scheduler` | Subclass of 'torch.optim.lr\_scheduler.LRScheduler' | optional, user specified lr\_scheduler instead of the default choice (StepLR). | None |
| `lr_scheduler_kwargs` | [dict](#dict) | optional, list of parameters used by the user specified `lr_scheduler`. | None |
| `dataloader_kwargs` | [dict](#dict) | optional, list of parameters passed into the PyTorch Lightning dataloader by the `TimeSeriesDataLoader`. | None |
| `**trainer_kwargs` | [int](#int) | keyword trainer arguments inherited from [PyTorch Lightning's trainer](https://pytorch-lightning.readthedocs.io/en/stable/api/pytorch_lightning.trainer.trainer.Trainer.html?highlight=trainer). | {} |
#### `MLP.fit`
```python theme={null}
fit(
dataset, val_size=0, test_size=0, random_seed=None, distributed_config=None
)
```
Fit.
The `fit` method, optimizes the neural network's weights using the
initialization parameters (`learning_rate`, `windows_batch_size`, ...)
and the `loss` function as defined during the initialization.
Within `fit` we use a PyTorch Lightning `Trainer` that
inherits the initialization's `self.trainer_kwargs`, to customize
its inputs, see [PL's trainer arguments](https://pytorch-lightning.readthedocs.io/en/stable/api/pytorch_lightning.trainer.trainer.Trainer.html?highlight=trainer).
The method is designed to be compatible with SKLearn-like classes
and in particular to be compatible with the StatsForecast library.
By default the `model` is not saving training checkpoints to protect
disk memory, to get them change `enable_checkpointing=True` in `__init__`.
**Parameters:**
| Name | Type | Description | Default |
| - | - | - | - |
| `dataset` | [TimeSeriesDataset](#TimeSeriesDataset) | NeuralForecast's `TimeSeriesDataset`, see [documentation](./tsdataset.html). | *required* |
| `val_size` | [int](#int) | Validation size for temporal cross-validation. | 0 |
| `random_seed` | [int](#int) | Random seed for pytorch initializer and numpy generators, overwrites model.**init**'s. | None |
| `test_size` | [int](#int) | Test size for temporal cross-validation. | 0 |
**Returns:**
| Type | Description |
| - | - |
| None | |
#### `MLP.predict`
```python theme={null}
predict(
dataset,
test_size=None,
step_size=1,
random_seed=None,
quantiles=None,
h=None,
explainer_config=None,
**data_module_kwargs
)
```
Predict.
Neural network prediction with PL's `Trainer` execution of `predict_step`.
**Parameters:**
| Name | Type | Description | Default |
| - | - | - | - |
| `dataset` | [TimeSeriesDataset](#TimeSeriesDataset) | NeuralForecast's `TimeSeriesDataset`, see [documentation](./tsdataset.html). | *required* |
| `test_size` | [int](#int) | Test size for temporal cross-validation. | None |
| `step_size` | [int](#int) | Step size between each window. | 1 |
| `random_seed` | [int](#int) | Random seed for pytorch initializer and numpy generators, overwrites model.**init**'s. | None |
| `quantiles` | [list](#list) | Target quantiles to predict. | None |
| `h` | [int](#int) | Prediction horizon, if None, uses the model's fitted horizon. Defaults to None. | None |
| `explainer_config` | [dict](#dict) | configuration for explanations. | None |
| `**data_module_kwargs` | [dict](#dict) | PL's TimeSeriesDataModule args, see [documentation](https://pytorch-lightning.readthedocs.io/en/1.6.1/extensions/datamodules.html#using-a-datamodule). | {} |
**Returns:**
| Type | Description |
| - | - |
| None | |
### Usage Example
```python theme={null}
import pandas as pd
import matplotlib.pyplot as plt
from neuralforecast import NeuralForecast
from neuralforecast.models import MLP
from neuralforecast.losses.pytorch import DistributionLoss
from neuralforecast.utils import AirPassengersPanel, AirPassengersStatic
Y_train_df = AirPassengersPanel[AirPassengersPanel.ds=AirPassengersPanel['ds'].values[-12]].reset_index(drop=True) # 12 test
model = MLP(h=12, input_size=24,
loss=DistributionLoss(distribution='Normal', level=[80, 90]),
scaler_type='robust',
learning_rate=1e-3,
max_steps=200,
val_check_steps=10,
early_stop_patience_steps=2)
fcst = NeuralForecast(
models=[model],
freq='ME'
)
fcst.fit(df=Y_train_df, static_df=AirPassengersStatic, val_size=12)
forecasts = fcst.predict(futr_df=Y_test_df)
# Plot predictions
Y_hat_df = forecasts.reset_index(drop=False).drop(columns=['unique_id','ds'])
plot_df = pd.concat([Y_test_df, Y_hat_df], axis=1)
plot_df = pd.concat([Y_train_df, plot_df])
plot_df = plot_df[plot_df.unique_id=='Airline1'].drop('unique_id', axis=1)
plt.plot(plot_df['ds'], plot_df['y'], c='black', label='True')
plt.plot(plot_df['ds'], plot_df['MLP-median'], c='blue', label='median')
plt.fill_between(x=plot_df['ds'][-12:],
y1=plot_df['MLP-lo-90'][-12:].values,
y2=plot_df['MLP-hi-90'][-12:].values,
alpha=0.4, label='level 90')
plt.grid()
plt.legend()
plt.plot()
```
## Related topics
- [NN Modules](/neuralforecast/common.modules.html.md)
- [Adding Models to NeuralForecast](/neuralforecast/docs/tutorials/adding_models.html.md)
- [Automatic Forecasting](/neuralforecast/models.html.md)
- [MLPMultivariate](/neuralforecast/models.mlpmultivariate.html.md)
- [Temporal Classification](/neuralforecast/docs/tutorials/temporal_classification.html.md)